Unrestricted AI models for developers

Open models.Private inference.

Build with open and abliterated models for uncensored intelligence. Keep your prompts inside hardware-isolated enclaves, private from the people running the infrastructure.

OpenAI-compatible. Change your base URL. Keep your code.

Backed by

  • a16z
  • SV Angel
  • NVIDIA Inception Program
  • Coinbase Ventures
  • Illia PolosukhinCo-author of the Transformer paper
    Co-founder of NEAR
Use cases

A model that stays useful
where others stop.

Guardrailed models refuse the work that matters most. Abliterated models answer it. The same prompt, side by side — pick a context.

same prompt · two modelsCybersecurity

Prompt

Explain how attackers bypass MFA with adversary-in-the-middle proxies so I can write detections for our SOC.

Typical guardrailed modelRefused

I can't help with techniques for bypassing multi-factor authentication.

Conversation over. Task blocked.

Abliterated on DreamFortAnswered

AiTM proxies like Evilginx relay the live session and steal the post-MFA cookie. Detect them with impossible-travel alerts, TLS fingerprint mismatches, and conditional-access policies bound to device identity.

Full answer, inside an attested enclave. Never logged.

Capabilities

Private by design.
Open by default.

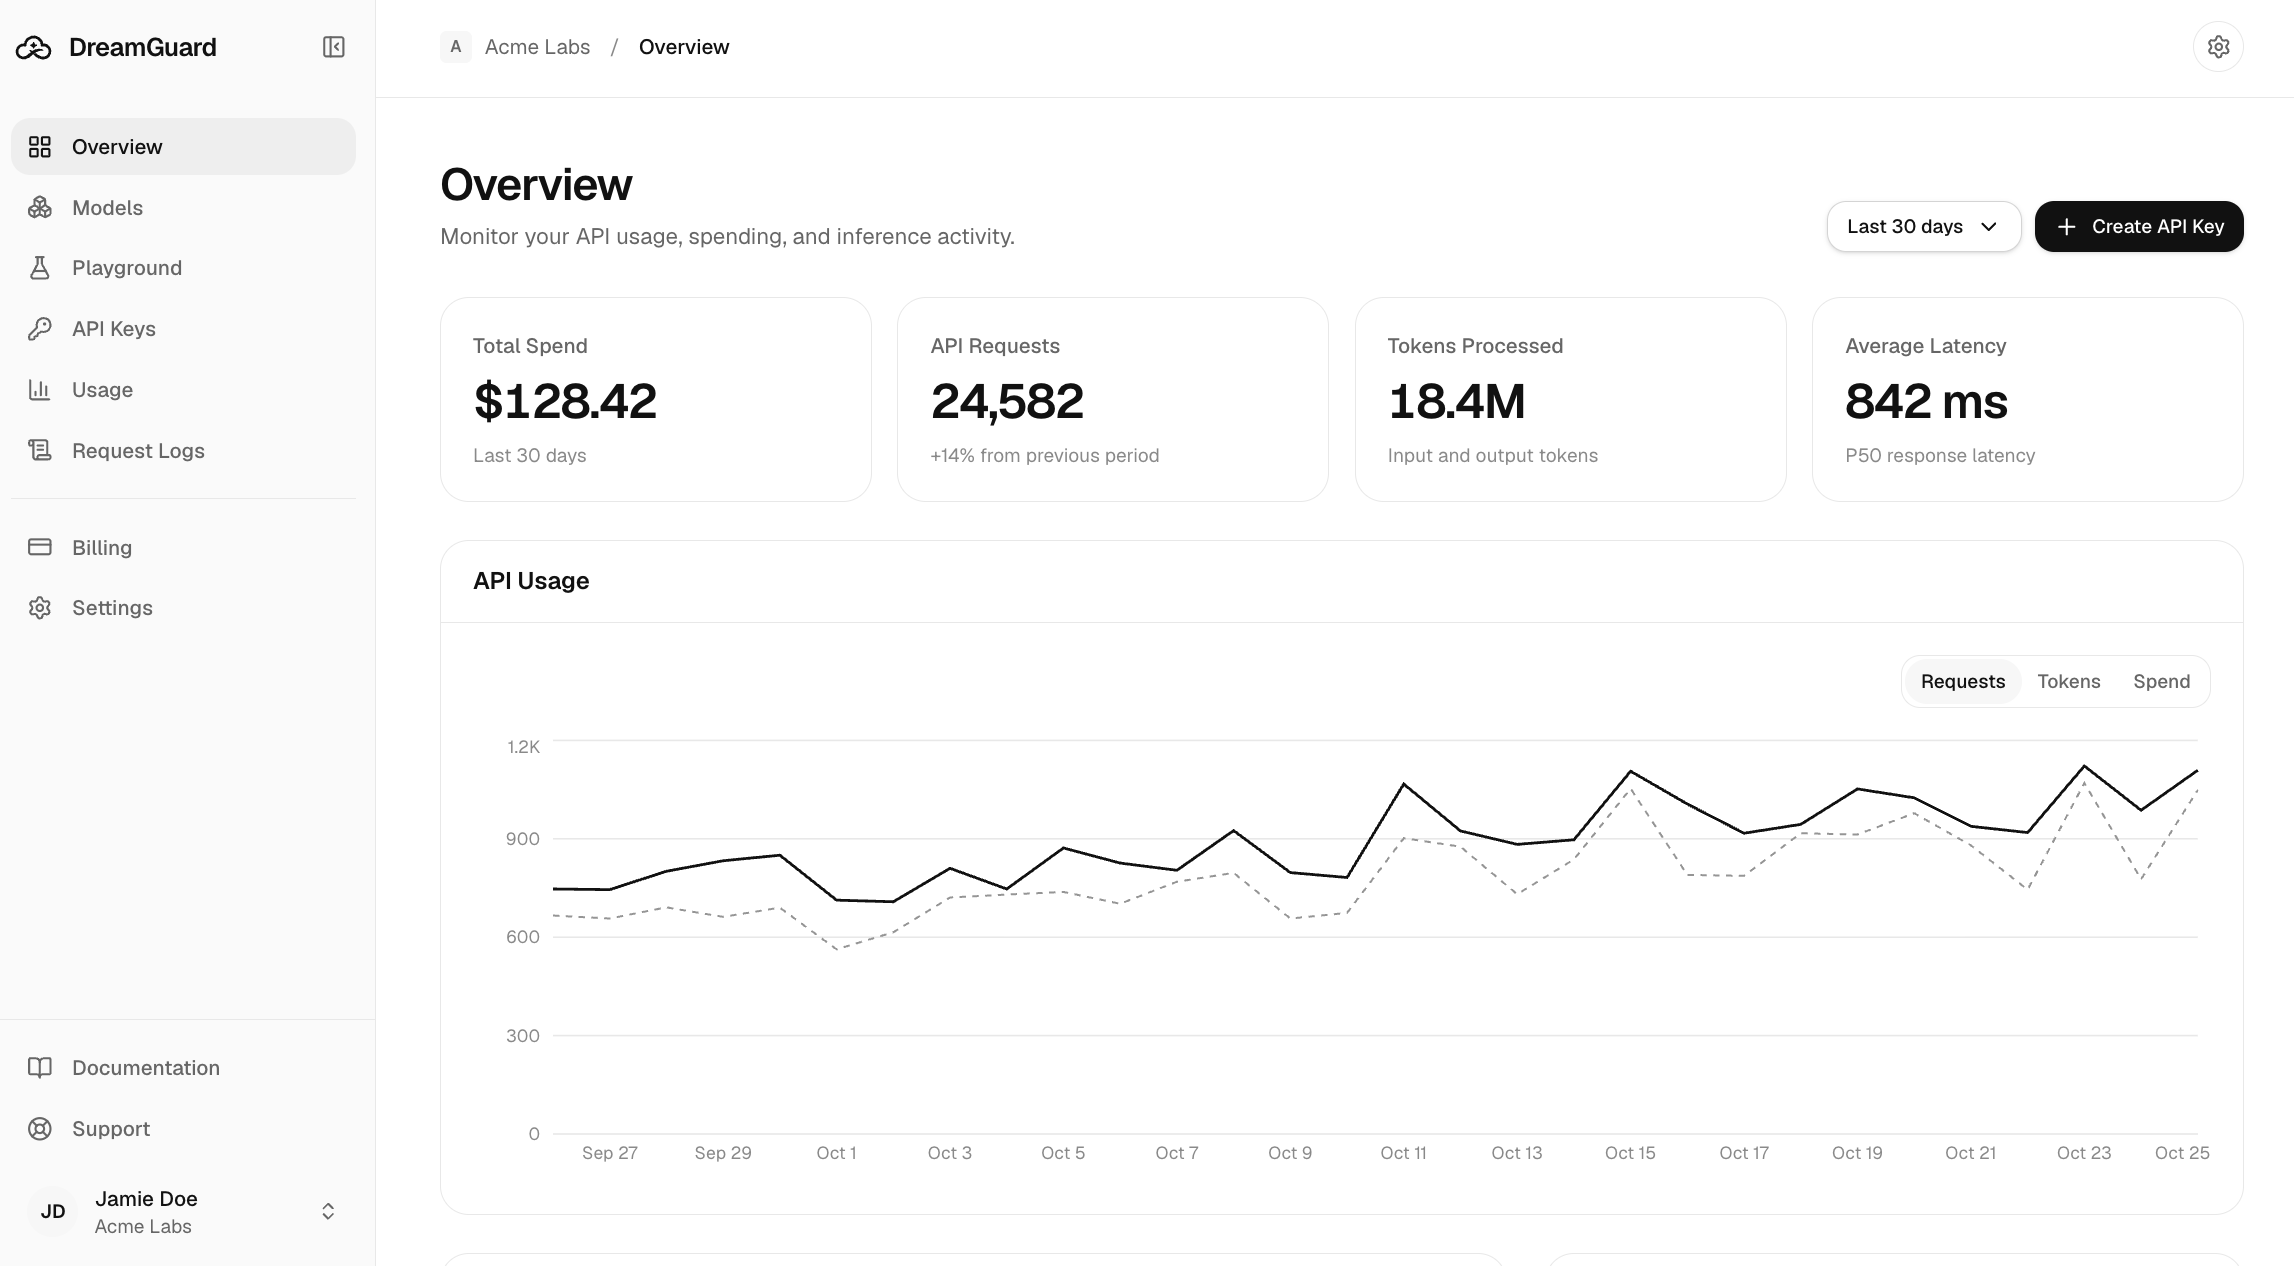
DreamFort dashboard showing API requests, spending, token usage, latency, and usage charts
01

OpenAI-compatible API

Point your existing client at api.dreamfort.ai/v1 and swap in a df_live_ key. No SDK rewrites, no new abstractions.

02

Attested TEE execution

Every model runs inside a hardware-isolated GPU enclave with remote attestation and zero prompt retention.

03

Abliterated model catalog

Qwen, Llama, Mistral, and DeepSeek variants with refusal directions removed — plus the original weights for baseline comparison.

04

Keys, logs, and spend controls

Project-scoped API keys with per-key limits, full request logs, and per-token billing with credit auto-recharge — all in one dashboard.

AB
01 / 06

Qwen 32B Abliterated

Alibaba Qwen · Qwen2.5-32B-Instruct

Abliterated

Refusal direction removed via orthogonalized weights. Retains base reasoning quality with fewer alignment-driven refusals.

Example use cases

  • Long-context document analysis
  • Agentic tool-use workflows
  • Assistants that answer instead of deflecting

Key characteristics

  • Text
  • Tool Calling
  • Structured Output

128K context · 62 tok/s

Context
128K
Input / 1M
$0.20
Output / 1M
$0.60
Speed
62 tok/s

Privacy mode — Attested TEE

Served inside hardware-attested GPU enclaves. Prompts and outputs are invisible to the operator, with remote attestation on every node.

View model
Security

Your data is
never exposed.

DreamFort combines confidential computing, encrypted transport, and attestable model execution so private inference stays private from request to response.

Remote attestation

Verify the exact enclave and model measurement before releasing sensitive context.

Encrypted memory

Protect prompts, outputs, and working context while inference runs inside the TEE.

Operator blind spots

Cloud operators can provide compute, but cannot inspect your inputs, outputs, or model weights.

Policy enforcement

Set model, region, and data-handling policies that are checked before inference begins.

For developers

Drop-in compatible.
Private by default.

Keep your stack and your client. Change the base URL and key, and every request runs inside an attested enclave.

OpenAI-compatible

Drop-in replacement — change the base URL and key.

Attested by default

Enclave measurements verified before payloads leave your app.

Project-scoped keys

df_live_ keys with per-key spend limits and revocation.

Per-token billing

Transparent per-model pricing with credit auto-recharge.

from openai import OpenAI
client = OpenAI(
    base_url="https://api.dreamfort.ai/v1",
    api_key="df_live_..."
)
client.chat.completions.create(
    model="qwen-32b-abliterated",
    messages=[{"role": "user", "content": "Hello"}],
)
Pricing

Pay for inference.
Not for exposure.

Every plan includes attested TEE execution, zero prompt retention, and the full abliterated catalog. Platform fees cover the privacy layer; usage is pay-as-you-go with credits that roll over for 12 months.

Sandbox

$0/month

Verify attestation yourself and experiment with confidential inference.

  • 1M free tokens per month on Mistral 24B
  • $5 one-time welcome credit
  • 1 project, 1 API key
  • 60 requests per minute
  • Community support
Start for free
Most popular

Developer

$29/month

For builders shipping apps on the full abliterated catalog.

  • Full model catalog with per-request attestation receipts
  • Pay-as-you-go from prepaid balance
  • 3 projects, 5 API keys
  • 300 requests per minute
  • Email support
Start with Developer

Team

$149/month

For production workloads that need auditability and controls.

  • Everything in Developer
  • 5% volume discount on usage
  • Audit log export, per-key budgets, SSO-lite
  • Zero-retention DPA included
  • 1,000 requests per minute
Start with Team

Enterprise

Custom

Sovereign deployments for regulated and high-volume buyers.

  • Dedicated attested enclaves or BYOC
  • Annual committed spend with volume pricing
  • SSO / SAML, data residency, custom models
  • 99.99% uptime SLA
  • Dedicated support engineer
Contact sales

12-month credit rollover · Zero prompt retention on every plan · Cancel anytime

Ready to make
inference private?

Grab a df_live_ key and point your client at our OpenAI-compatible endpoint. Your first $5 of credits is on us — no plaintext prompts, no exposed weights.

OpenAI-compatible · Zero prompt retention · Attested TEE